Walk into any busy bar, conference hall, or family gathering and within seconds, one voice will cut through the noise before your brain has consciously registered it. It happens faster than thought, and most people couldn’t explain why. It turns out the answer is less about volume and more about a surprisingly precise set of biological, acoustic, and psychological factors that researchers are still actively mapping.
The Cocktail Party Effect: Your Brain Is Already Filtering
The phenomenon is known as the cocktail party effect, where a listener can engage in a single conversation despite other distractions, such as multiple conversations occurring simultaneously around them. This isn’t passive; it’s an active, ongoing process in your auditory system. The ability to focus on a particular conversation in a noisy and crowded room is termed selective attention, a cognitive process that allows us to concentrate on a specific auditory stream while ignoring irrelevant background noise. The sheer speed of this filtering is what makes certain voices so powerful: by the time you realize you’re listening, the decision has already been made for you.
Pitch Is the Brain’s Primary Trigger
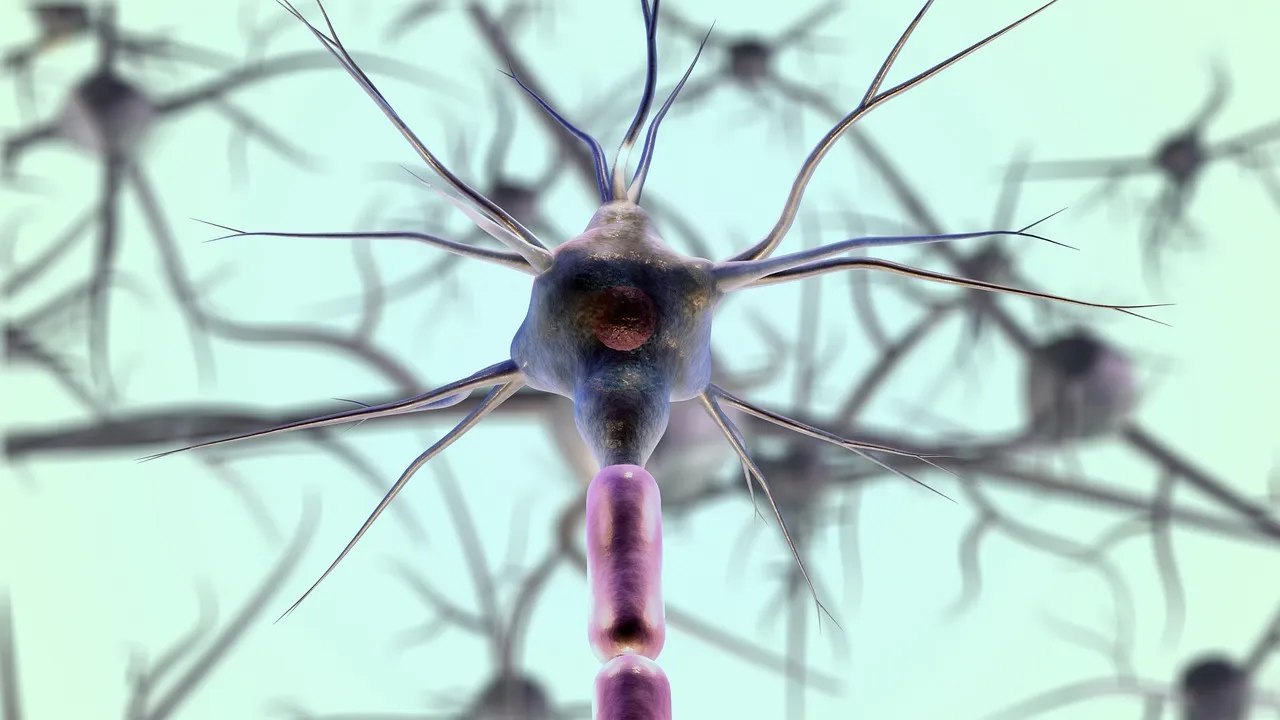
Scientists have discovered that a group of neurons in the brain’s auditory stem help us to tune into specific conversations in a crowded room. In order to focus on a particular conversation, listeners need to be able to focus on the voice of the speaker they wish to listen to, a process called selective attention, which has long been known to happen in the part of the brain called the auditory cortex. What’s more recent and more surprising is where the triggering begins. Research from Imperial College London shows that the pitch of the speaker’s voice is an important cue used in the auditory brainstem to focus on a target speaker. Pitch, in other words, is not just an aesthetic quality. It’s a neural compass.
How Resonance and Fundamental Frequency Shape Attention
Most research on the acoustic parameters that influence vocal attractiveness has focused on the possible roles of sexually dimorphic characteristics of voices, such as fundamental frequency, which refers to pitch, and formant frequencies, which correlate with body size. A 2024 study published in Scientific Reports went further and found that fundamental frequency was negatively correlated with male vocal attractiveness and positively correlated with female vocal attractiveness. This means deeper male voices and higher female voices tend to hold attention more readily, not because of cultural preference alone, but because of how the auditory system is tuned. A voice reads as compelling based on a combination of pitch, resonance, rhythm, and emotional tone, with the specific mix shifting depending on the listener’s sex, hormonal state, and cultural background.
Charisma Is Measurable in Acoustic Data
A 2025 study applied explainable machine learning to identify which vocal attributes in a lecturer’s speech influence students’ views of a lecturer’s charisma, a key contributor to teaching quality. The researchers analyzed speech from 200 native-English lecturers rated by 900 students. Higher levels and a larger variability of pitch, loudness, and rhythm have been associated with charismatic speakers. The implication is striking: charisma, often described as something felt rather than measured, leaves a consistent acoustic fingerprint. Same-gender evaluations of charisma were mainly based on pitch, while cross-gender evaluations rely mostly on loudness or rhythm.
The Lombard Effect: Noise Makes Compelling Voices More Compelling
The so-called Lombard effect intuitively leads to an increase in voice intensity, pitch, and phonation time when speaking in noisy environments. Most people do this unconsciously, but the effect is uneven. Some speakers naturally adjust in ways that preserve clarity and authority; others strain and lose definition. Having to make oneself heard over noise results in higher sound pressure level and higher fundamental frequency, alongside increased phonation time. Speakers who can ride the Lombard effect without losing vocal quality end up with what sounds, to listeners, like effortless projection.
Vocal Persona: The Strategic Layer Most People Don’t Notice
To ensure intelligibility in noisy or reverberant environments, experienced speakers either choose assertive or authoritative personas or accentuate key vocal characteristics of their current persona. Research published in Frontiers in Computer Science in 2025 found that participants reported using between two to seven different vocal personas tailored to various specific contexts. This is a remarkable range of vocal flexibility that most people exercise without any formal training. Vocal persona is a dynamic, context-responsive set of vocal behaviors that frames and bounds expressive interactions while centering the speaker’s agency.
Confidence and Likeability Are Heard, Not Just Seen
Recent findings show that speakers deliberately modulate their vocal expressions to accentuate traits such as confidence and likeability, aligning these adjustments with perceptual dimensions of affiliation and competence. This happens through subtle changes in pacing, emphasis, and vocal weight, not just through what is said. Vocal attributes have been found to contribute to specific behavioral constructs, such as confidence and persuasion. When a voice projects calm certainty in a noisy room, listeners register it as trustworthiness before processing the actual words.
Distinctiveness Beats Averageness
Research has found that increasing vocal averageness significantly decreases distinctiveness ratings, demonstrating that listeners can detect when a voice blends toward the generic mean. A voice that sounds like everyone else is easy to filter out. The auditory system, by its very design, is wired to flag novelty and contrast. Results suggest that averageness may not significantly increase attractiveness judgments of voices and are consistent with previous work reporting significant associations between attractiveness and voice pitch. Standing out, even in pitch or timing alone, keeps a voice from dissolving into the ambient noise.
The Brain Converts Attended Voices Into Language Differently
Using EEG brainwave recordings, researchers found that the story participants were instructed to pay attention to was converted into linguistic units known as phonemes, which are units of sound that can distinguish one word from another, while the other story was not. This is more than selective hearing; it’s a selective translation process happening in real time. Humans have the remarkable ability to selectively focus on a single talker in the midst of other competing talkers, though the neural mechanisms that underlie this phenomenon remain incompletely understood. What researchers at the University of Rochester Medical Center were able to show is that the brain essentially “commits” to one voice on an acoustic level before the listener makes any conscious choice.
Sociocultural Context Shapes Which Voices We Prioritize
Sociocultural context emerged as a powerful influence in vocal perception research, and many participants referred to their voice as an outward-facing communication channel of personality. Authority, gender, familiarity, and even the setting itself (a lecture hall versus a noisy bar) change which voices rise to the top of the auditory stack. A study published in 2025 examined the charisma signal, voice pitch, and their interaction in leader selection, measuring perceptions of hirability, competence, and warmth. Across three pre-registered experiments involving over two thousand participants, the charisma signal was found to increase female applicants’ perceived hirability. The voices we single out in a crowd are shaped as much by who we expect to hear as by the acoustic signal itself.
The Takeaway
Voice is not a single thing. It’s pitch, rhythm, resonance, timing, and emotional tone working simultaneously, processed by a brain that makes snap judgments before conscious thought arrives. The voices that cut through a crowded room aren’t necessarily the loudest. They’re the ones that carry the right contrast, the right distinctiveness, and often a calibrated confidence that the auditory brainstem finds simply harder to ignore.
What the research makes clear is that some of these qualities are natural, while others are deliberately learned and adjusted in real time. Understanding the mechanics behind vocal attention doesn’t diminish the power of a compelling voice. If anything, it deepens the appreciation for how much information travels in a single sentence spoken well.
AI Disclaimer: This article was created with the assistance of AI tools and reviewed by a human editor.